Mathematics · Ch 7 — Statistics
Mean Deviation for Grouped Data
Mean Deviation for Grouped Data
Mean Deviation for Grouped Data
Data can be grouped in two ways: as a discrete frequency distribution (where each observation is a distinct value with its own frequency) or as a continuous frequency distribution (where data is divided into class intervals). The method for finding mean deviation differs slightly between the two, but the core idea remains the same — we measure the average absolute distance of the data from a central value.
(a) Discrete Frequency Distribution
Suppose we have distinct values occurring with frequencies respectively. The data is arranged as:
Here is the total number of observations.
(i) Mean Deviation About the Mean
Step 1 — Find the mean.
The mean of the grouped data is:
Step 2 — Find absolute deviations from the mean.
For each observation , compute .
Step 3 — Find the weighted mean of these absolute deviations.
Multiply each absolute deviation by its frequency, sum them up, and divide by :
The deviations are taken in absolute value — signs are ignored. If you sum the signed deviations , you will always get zero. That is why we use absolute values.
Example 4 — Find the mean deviation about the mean for:
| 2 | 5 | 6 | 8 | 10 | 12 | |
|---|---|---|---|---|---|---|
| 2 | 8 | 10 | 7 | 8 | 5 |
Solution. First compute the mean:
Now compute and :
| 2 | 2 | 4 | 5.5 | 11 |
| 5 | 8 | 40 | 2.5 | 20 |
| 6 | 10 | 60 | 1.5 | 15 |
| 8 | 7 | 56 | 0.5 | 3.5 |
| 10 | 8 | 80 | 2.5 | 20 |
| 12 | 5 | 60 | 4.5 | 22.5 |
| Total | 40 | 300 | 92 |
(ii) Mean Deviation About the Median
Step 1 — Find the median.
Arrange the observations in ascending order. Compute cumulative frequencies. The median is the value of the observation whose cumulative frequency is equal to or just greater than .
If is even, the median is the average of the -th and -th observations. Both lie in the same class when the cumulative frequency first reaches or exceeds .
Step 2 — Find absolute deviations from the median.
For each , compute , where is the median.
Step 3 — Find the weighted mean of these absolute deviations.
Example 5 — Find the mean deviation about the median for:
| 3 | 6 | 9 | 12 | 13 | 15 | 21 | 22 | |
|---|---|---|---|---|---|---|---|---|
| 3 | 4 | 5 | 2 | 4 | 5 | 4 | 3 |
Solution. The data is already in ascending order. Compute cumulative frequencies:
| 3 | 6 | 9 | 12 | 13 | 15 | 21 | 22 | |
|---|---|---|---|---|---|---|---|---|
| 3 | 4 | 5 | 2 | 4 | 5 | 4 | 3 | |
| c.f. | 3 | 7 | 12 | 14 | 18 | 23 | 27 | 30 |
, so . The 15th and 16th observations both lie in the cumulative frequency 18, which corresponds to . Therefore:
Now compute and :
| 3 | 10 | 3 | 30 |
| 6 | 7 | 4 | 28 |
| 9 | 4 | 5 | 20 |
| 12 | 1 | 2 | 2 |
| 13 | 0 | 4 | 0 |
| 15 | 2 | 5 | 10 |
| 21 | 8 | 4 | 32 |
| 22 | 9 | 3 | 27 |
| Total | 30 | 149 |
(b) Continuous Frequency Distribution
In a continuous frequency distribution, data is grouped into class intervals without gaps. For example:
| Marks | 0-10 | 10-20 | 20-30 | 30-40 | 40-50 | 50-60 |
|---|---|---|---|---|---|---|
| Students | 12 | 18 | 27 | 20 | 17 | 6 |
The key assumption: the frequency in each class is centred at its mid-point. So we first find the mid-point of each class, then proceed exactly as for a discrete frequency distribution.
(i) Mean Deviation About the Mean
Step 1 — Find the mid-point of each class.
For a class , the mid-point is .
Step 2 — Compute the mean .
Use the same formula as for discrete data:
Step 3 — Compute absolute deviations and their weighted sum.
Then:
Example 6 — Find the mean deviation about the mean for:
| Marks | 10-20 | 20-30 | 30-40 | 40-50 | 50-60 | 60-70 | 70-80 |
|---|---|---|---|---|---|---|---|
| Students | 2 | 3 | 8 | 14 | 8 | 3 | 2 |
Solution. Compute mid-points and the required columns:
| Class | |||||
|---|---|---|---|---|---|
| 10-20 | 2 | 15 | 30 | 30 | 60 |
| 20-30 | 3 | 25 | 75 | 20 | 60 |
| 30-40 | 8 | 35 | 280 | 10 | 80 |
| 40-50 | 14 | 45 | 630 | 0 | 0 |
| 50-60 | 8 | 55 | 440 | 10 | 80 |
| 60-70 | 3 | 65 | 195 | 20 | 60 |
| 70-80 | 2 | 75 | 150 | 30 | 60 |
| Total | 40 | 1800 | 400 |
Shortcut Method (Step-Deviation Method) for Mean Deviation About the Mean
When the mid-points are large, we can simplify the calculation of using step deviations. This involves shifting the origin (choosing an assumed mean ) and changing the scale (dividing by a common factor ).
Define a new variable:
where is the assumed mean (usually a mid-point near the centre of the data) and is the common factor (the class width, if all classes have equal width).
Then the mean is:
The step-deviation method only simplifies the calculation of . The rest of the procedure — finding and then — remains exactly the same. You still need to compute the actual absolute deviations from the actual mean.
Example 6 using step-deviation method.
Take (the mid-point of the 40-50 class) and (the class width).
| Class | ||||||
|---|---|---|---|---|---|---|
| 10-20 | 2 | 15 | -3 | -6 | 30 | 60 |
| 20-30 | 3 | 25 | -2 | -6 | 20 | 60 |
| 30-40 | 8 | 35 | -1 | -8 | 10 | 80 |
| 40-50 | 14 | 45 | 0 | 0 | 0 | 0 |
| 50-60 | 8 | 55 | 1 | 8 | 10 | 80 |
| 60-70 | 3 | 65 | 2 | 6 | 20 | 60 |
| 70-80 | 2 | 75 | 3 | 6 | 30 | 60 |
| Total | 40 | 0 | 400 |
The result is identical, as expected.
(ii) Mean Deviation About the Median
The process is similar to the discrete case, but we must first find the median using the formula for continuous data.
Step 1 — Find the median class.
Arrange the data in ascending order (the classes are already in order). Compute cumulative frequencies. The median class is the class interval whose cumulative frequency is just greater than or equal to .
Step 2 — Apply the median formula.
where:
- = lower limit of the median class
- = frequency of the median class
- = width of the median class
- = cumulative frequency of the class just preceding the median class
- = total frequency …
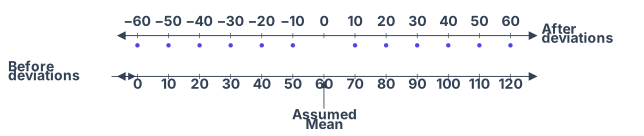
Drawn by us to help you understand the concept clearly, and verified to make sure it's accurate. For exams, practice from your textbook's own diagram.
Fig. 13.3 is a visual of the core idea behind the step-deviation method: you can shift the origin of your number line to a convenient assumed mean, work with smaller numbers, and then shift back at the end.
The figure shows two aligned number lines, one above the other. The bottom line is the original data scale, running from 0 to 120. The top line is the deviation scale, running from −60 to 60. Each tick mark on the bottom line has a corresponding tick directly above it on the top line. The key alignment is at the value 60 on the bottom line: directly above it, on the top line, sits the deviation 0. An upward arrow labelled "Assumed Mean" points to 60 on the bottom line.
What this teaches is that subtracting the assumed mean from every observation is equivalent to sliding the entire number line leftwards so that the origin (0 on the deviation line) now sits at the assumed mean. The deviations are the new coordinates on the shifted line. If all these deviations also share a common factor (like all being multiples of 10), you can further scale them down by dividing by , giving the step-deviations . This is a change of scale on the number line, shown separately in Fig. 13.4.
The textbook uses this figure to introduce the step-deviation formula for the mean:
Here, is the assumed mean (the point to which you shift the origin), is the common factor (the scale divisor), are the step-deviations, are the frequencies, and is the total frequency. The formula says: compute the mean of the step-deviations, multiply by to undo the scaling, then add to undo the shift. The figure makes it clear that this is just a two-step translation of the number line — first a shift, then a rescaling — and that the mean follows the same transformation. …
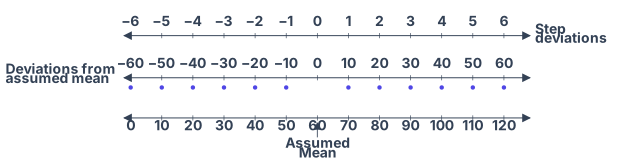
Drawn by us to help you understand the concept clearly, and verified to make sure it's accurate. For exams, practice from your textbook's own diagram.
Fig. 13.4 is a visual explanation of the step-deviation method — a shortcut for calculating the mean of grouped data when the class intervals are equal. The figure shows three horizontal number lines, one above the other, all aligned vertically so that the same tick marks line up.
The bottom number line is the original raw scale, running from 0 to 120. This is the scale on which the actual data (mid-points of classes) live. The middle number line shows "deviations from assumed mean" — it runs from −60 to +60. Each tick on this line corresponds to the difference between a raw value and the assumed mean, which is chosen as 60. The indigo dots on each tick mark the actual deviation values. An upward arrow labelled "Assumed Mean" points to the 60 mark on the bottom scale, making it clear that the origin of the middle line has been shifted to that point.
The top number line shows "step deviations" — it runs from −6 to +6. This is the result of dividing every deviation from the middle line by a common factor (here, 10). So the step deviation is simply the deviation divided by the class width.
The key idea the figure teaches is that you can simplify calculations by first shifting the origin (subtracting an assumed mean) and then changing the scale (dividing by the common factor). This transforms the original mid-points into step deviations using:
where is the assumed mean (60 in the figure) and is the common factor (10 in the figure). The mean of the original data can then be recovered by reversing both transformations:
Here, is the total frequency. The textbook uses this method to compute the mean for the data in Example 6 (marks of students), where and , and then finds the mean deviation about the mean using the usual formula:
The step-deviation method does not change the value of the mean deviation itself — it only simplifies the calculation of . Once is found, the deviations are computed directly from the original mid-points, not from the step deviations.
A common mistake is to think that the step deviations can be used directly in the mean deviation formula. They cannot — the mean deviation requires absolute differences from the actual mean , not from the assumed mean. The step-deviation trick works only for computing itself. …
| 2 | 2 | 4 | 5.5 | 11 |
| 5 | 8 | 40 | 2.5 | 20 |
| 6 | 10 | 60 | 1.5 | 15 |
| 8 | 7 | 56 | 0.5 | 3.5 |
| 10 | 8 | 80 | 2.5 | 20 |
| 3 | 6 | 9 | 12 | 13 | 15 | 21 | 22 | |
|---|---|---|---|---|---|---|---|---|
| 3 | 4 | 5 | 2 | 4 | 5 | 4 | 3 |
| 10 | 7 | 4 | 1 | 0 | 2 | 8 | 9 | |
|---|---|---|---|---|---|---|---|---|
| 3 | 4 | 5 | 2 | 4 | 5 | 4 | 3 |
| Marks obtained | Number of students | Mid-points | |||
|---|---|---|---|---|---|
| 10-20 | 2 | 15 | 30 | 30 | 60 |
| 20-30 | 3 | 25 | 75 | 20 | 60 |
| 30-40 | 8 | 35 | 280 | 10 | 80 |
| 40-50 | 14 | 45 | 630 | 0 | 0 |
| 50-60 | 8 | 55 | 440 | 10 | 80 |
| Marks obtained | Number of students | Mid-points | ||||
|---|---|---|---|---|---|---|
| 10-20 | 2 | 15 | 30 | 60 | ||
| 20-30 | 3 | 25 | 20 | 60 | ||
| 30-40 | 8 | 35 | 10 | 80 | ||
| 40-50 | 14 | 45 | 0 | 0 | 0 | 0 |
| 50-60 | 8 | 55 | 1 | 8 | 10 | 80 |
| Class | Frequency | Cumulative frequency | Mid-points | ||
|---|---|---|---|---|---|
| 0-10 | 6 | 6 | 5 | 23 | 138 |
| 10-20 | 7 | 13 | 15 | 13 | 91 |
| 20-30 | 15 | 28 | 25 | 3 | 45 |
| 30-40 | 16 | 44 | 35 | 7 | 112 |