Mathematics · Ch 13 — Statistics
Introduction
Introduction
The Need for Measures of Dispersion
Statistics deals with data collected for a specific purpose. We make decisions about the data by analysing and interpreting it. In earlier classes, you learned how to represent data graphically (bar graphs, histograms, frequency polygons) and in tabular form. This representation reveals certain broad features of the data — its shape, its extremes, and where most values lie.
You also studied the three measures of central tendency: the mean (arithmetic mean), the median, and the mode. Each of these gives us a single representative value around which the data points are centred. Recall the mean of observations :
The median is found by first arranging the data in ascending (or descending) order. If the number of observations is odd, the median is the observation. If is even, the median is the mean of the and observations.
A measure of central tendency gives us a rough idea of where the data is centred — but on its own it says nothing about how the data is scattered or bunched around that centre. To interpret data properly, we also need to know how spread out it is.
Two Batsmen, the Same Average
Consider the runs scored by two batsmen, A and B, in their last ten matches:
Batsman A: 30, 91, 0, 64, 42, 80, 30, 5, 117, 71
Batsman B: 53, 46, 48, 50, 53, 53, 58, 60, 57, 52
Working out the mean and median for each:
For Batsman A:
Arranging A's scores in ascending order: 0, 5, 30, 30, 42, 64, 71, 80, 91, 117. Since (even), the median is the mean of the 5th and 6th observations:
For Batsman B:
Arranging B's scores in ascending order: 46, 48, 50, 52, 53, 53, 53, 57, 58, 60. The median is again the mean of the 5th and 6th observations:
| Batsman A | Batsman B | |
|---|---|---|
| Mean | 53 | 53 |
| Median | 53 | 53 |
Both batsmen have exactly the same mean (53) and the same median (53). Can we say, then, that the two performances are the same? Clearly not. The scores of Batsman A vary from a minimum of 0 to a maximum of 117 — a very wide swing. Batsman B's scores, on the other hand, vary only from 46 to 60 — a tight, consistent band.
Seeing the Difference
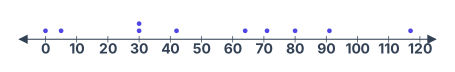
Let us now plot the ten scores of each batsman as dots on a number line. We get the following two diagrams:
Drawn by us to help you understand the concept clearly, and verified to make sure it's accurate. For exams, practice from your textbook's own diagram.
What Fig. 13.1 Shows
The figure is a simple number line running from 0 to 120, with tick marks every 10 units and double arrowheads at both ends. Ten indigo dots are placed along this line, each representing one of Batsman A's scores from his last ten matches: 0, 5, 30, 30, 42, 64, 71, 80, 91, and 117. The two scores of 30 are stacked vertically so both are visible. The dots are spread across nearly the entire length of the line — from 0 all the way to 117 — with large gaps between them.
This is not a frequency distribution or a histogram. There is no vertical axis, no curve, and no second panel. The only visual element is the one-dimensional scatter of points on the number line. The purpose is to show, at a glance, how far apart the individual scores are from one another and from the centre of the data.
The Physical Idea It Teaches
The figure drives home a critical point that the textbook makes immediately before introducing it: two data sets can have the same mean and the same median yet be fundamentally different. Batsman A and Batsman B both average 53 runs per match, and both have a median of 53. But look at the spread. Batsman A's scores range from 0 to 117 — a span of 117 runs. Batsman B's scores, shown in a companion figure (Fig. 13.2), range only from 46 to 60, a span of 14 runs. The dots for Batsman B cluster tightly around 53; the dots for Batsman A are scattered widely.
The figure therefore introduces the concept of dispersion — the degree to which data points are spread out. A measure of central tendency (mean, median, mode) tells you where the data are centred, but it tells you nothing about how much the data vary. Two data sets with identical centres can have wildly different variability. To fully describe a data set, you need both a measure of central tendency and a measure of dispersion.
The Key Formula the Textbook Develops with This Figure
The textbook uses the contrast between Batsman A and Batsman B to motivate the need for a single number that quantifies spread. The simplest such number is the range:
For Batsman A: .
For Batsman B: .
The range is easy to compute and gives a rough idea of spread, but it has a serious limitation: it depends only on the two extreme values and ignores everything in between. The textbook goes on to develop better measures — mean deviation, variance, and standard deviation — that use every observation. Those formulas are built on the foundation that Fig. 13.1 provides: the visual intuition that some data sets are tightly bunched and others are widely scattered.
The range is sensitive to outliers. A single extreme score, like Batsman A's 117, can make the range very large even if most scores are moderate. That is why the range is rarely used alone in serious analysis.
The mean of Batsman A's scores is calculated as:
The median, after sorting the data in ascending order (0, 5, 30, 30, 42, 64, 71, 80, 91, 117), is the average of the 5th and 6th observations: . Both measures match Batsman B's exactly, yet the two performances are clearly not the same. Fig. 13.1 makes that difference visible before any formula is introduced.
Drawn by us to help you understand the concept clearly, and verified to make sure it's accurate. For exams, practice from your textbook's own diagram.
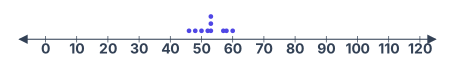
The figure is a dot plot — a simple number line drawn from 0 to 120, with each of Batsman B’s ten scores placed as a dot above its value. The ten scores are: 46, 48, 50, 52, 53, 53, 53, 57, 58, 60. Because three of them are 53, those three dots are stacked vertically at the 53 mark. Every other score appears exactly once, so each gets a single dot.
The horizontal axis is the runs scored, from 0 to 120. There is no vertical axis in the usual sense — the vertical stacking is only to show multiple observations at the same value. The entire set of dots lies between 46 and 60, a span of just 14 runs. That tight clustering is the whole point: it shows low dispersion. The data are bunched close together, and therefore close to the mean (53) and the median (53). The figure is the visual counterpart to the earlier dot plot for Batsman A (Fig. 13.1), whose dots are scattered from 0 to 117 — a range of 117 runs. By placing the two plots side by side, the textbook makes the idea of dispersion immediate: two data sets can have the same centre but very different spreads.
The figure does not show any curve, frequency polygon, or box plot. It is a pure dot plot — one of the simplest possible displays of raw data. The only "curve" is the mental image of how tightly the dots cluster.
The physical idea the figure teaches is that central tendency alone is not enough. Mean and median both equal 53 for both batsmen, yet the two performances are clearly different. Batsman B is consistent (low dispersion); Batsman A is erratic (high dispersion). To describe a data set fully, we need a measure of how spread out the data are — a measure of dispersion.
The textbook uses this figure to motivate the formal measures that follow. The first and simplest is the range:
For Batsman B, range . For Batsman A, range . The range already captures the difference in spread, but it uses only the two extreme values and ignores everything in between. That limitation leads to more sophisticated measures — mean deviation, variance, and standard deviation — all of which use every observation and measure how far, on average, the data lie from the mean.
The dot plot for Batsman B is the textbook’s first concrete example of low dispersion: data points are concentrated near the mean. The corresponding formula that quantifies this concentration is the variance (introduced later in the chapter), which for ungrouped data is
where is the mean, are the observations, and is the number of observations. A small variance means low dispersion — exactly what the figure shows.
In short, Fig. 13.2 is a visual anchor. It lets you see low dispersion before you calculate it. When you later compute the variance or standard deviation for Batsman B, you should expect a small number — and the dot plot tells you why.
The dots for Batsman B are close together, clustering tightly around the measure of central tendency (53). The dots for Batsman A are scattered far apart, spread out well beyond and below the centre. So although the two batsmen have identical averages, one is far more consistent than the other — and that difference is invisible if you look only at the mean or the median.
The measures of central tendency alone are insufficient to describe a dataset completely. They tell you where the centre is, but not how the data is spread around that centre. This spread — or variability — is a separate and equally important characteristic of the data.
Measuring the Spread
Variability is another factor that needs to be studied in statistics, alongside central tendency. Just as we use a single number (mean, median, or mode) to describe where data is centred, we want a single number to describe how it varies. This number is called a measure of dispersion.
In this chapter, you will learn some of the important measures of dispersion and how to calculate them, for both ungrouped data (raw data) and grouped data (data organised into frequency distributions).
A measure of central tendency and a measure of dispersion together give a much more complete picture of a dataset than either one alone. For the batsmen example above, the mean and median are identical, but the dispersion is vastly different — and that difference is crucial for judging real performance.