Mathematics · Ch 13 — Statistics
Variance and Standard Deviation
Variance and Standard Deviation
Why Squaring the Deviations?
When we calculated the mean deviation, we took absolute values of the deviations to prevent positive and negative deviations from cancelling each other out. But absolute values are mathematically awkward — they are not differentiable at zero and don't behave nicely in further calculations.
A much cleaner approach is to square each deviation. Since a square is always non-negative, the sign problem vanishes automatically. If we have observations with mean , then the sum
is always zero or positive. If this sum is exactly zero, then every single deviation must be zero — meaning all observations are identical to the mean, and there is no dispersion at all. If the sum is small, the observations cluster close to the mean (low dispersion). If it is large, the observations are spread far from the mean (high dispersion).
So far, this sum seems like a reasonable measure of scatter. But there is a serious flaw, as the textbook demonstrates with two contrasting data sets.
The Flaw in Using the Sum of Squared Deviations Directly
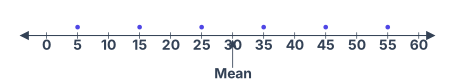
Consider Set A: six observations — 5, 15, 25, 35, 45, 55. Their mean is . The sum of squared deviations is
Now consider Set B: 31 observations — 15, 16, 17, …, 45. Their mean is also . The sum of squared deviations is
This is twice the sum of squares of the first 15 natural numbers (since contributes nothing):
If we judged dispersion by the raw sum of squared deviations, we would say Set A (sum = 1750) has less dispersion than Set B (sum = 2480). But look at the actual spread: Set A's deviations range from to , while Set B's deviations only range from to . The observations in Set A are clearly more scattered from the mean. The sum of squared deviations is misleading here because it depends on the number of observations — Set B has many more terms, so its sum is larger even though each individual deviation is smaller.
The raw sum is not a proper measure of dispersion because it grows with the sample size. A set with many tightly clustered observations can have a larger sum than a set with fewer, more scattered observations.
The Solution: Variance — the Mean of the Squared Deviations
To remove the dependence on the number of observations, we take the average of the squared deviations. This quantity is called the variance, denoted by (sigma squared).
For Set A, the mean of the squared deviations is
For Set B, it is
…
Drawn by us to help you understand the concept clearly, and verified to make sure it's accurate. For exams, practice from your textbook's own diagram.
Fig. 13.5 is a simple number-line diagram that makes a subtle but critical point about how we measure scatter. The line runs from 0 to 60, with tick marks every 5 units. Six dots sit at 5, 15, 25, 35, 45, and 55 — evenly spaced, far apart. An upward arrow labelled "Mean" points to 30, right in the centre. The caption calls this "large scatter", and the visual is unmistakable: the points are spread over a range of 50 units, from 5 to 55, with deviations as large as –25 and +25 from the mean.
The textbook uses this figure to expose a flaw in a naive measure of dispersion. If you simply add up the squared deviations from the mean — — you get 1750 for this set of six numbers. That sum is large in absolute terms. But compare it to Set B (31 observations from 15 to 45, also centred at 30), whose sum of squared deviations is 2480 — even larger. If you judged dispersion by the raw sum alone, you'd wrongly conclude that Set B is more spread out. The diagram shows the opposite: the six points in Fig. 13.5 are clearly more scattered than the tightly packed 31 points of Set B (shown in a separate figure, Fig. 13.6). The raw sum is misleading because it depends on the number of observations, not just the spread.
The solution the textbook develops is to take the mean of the squared deviations — the variance. For the six points in Fig. 13.5:
For Set B, the variance is . Now the numbers match the visual: the variance for the widely spaced six points is much larger, correctly reflecting the "large scatter" the figure shows.
where is the variance, is the number of observations, are the individual observations, and is their mean. …
Drawn by us to help you understand the concept clearly, and verified to make sure it's accurate. For exams, practice from your textbook's own diagram.
What Fig. 13.6 Shows
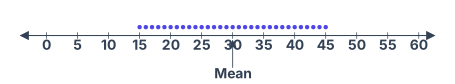
The figure presents a number line from 0 to 60. Thirty-one indigo dots sit at every integer from 15 to 45 — a dense, continuous block of points. An upward arrow labelled "Mean" points to the value 30, which is the centre of this block. The visual message is immediate: the observations are packed tightly around the mean, with the farthest points only 15 units away on either side.
This is the companion to Fig. 13.5, which showed Set A — six widely scattered points (5, 15, 25, 35, 45, 55) also centred at 30. Together, the two figures make a single pedagogical point: raw scatter looks different from what the sum of squared deviations alone suggests.
The Physical Idea
The textbook has just introduced the sum of squared deviations from the mean, , as a candidate measure of dispersion. For Set A (six points), this sum is 1750. For Set B (31 points), it is 2480. If you used only the raw sum, you would conclude that Set B has more dispersion — yet the figure shows the opposite: Set B's points are far more concentrated near the mean.
The problem is that the raw sum grows with the number of observations. A larger dataset naturally produces a larger total, even if each individual point is closer to the mean. The figure makes this contradiction visually obvious: the dense cluster of 31 points clearly has less scatter than the sparse six-point set, but the raw sum says otherwise.
The Resolution: Variance
To correct for the number of observations, we take the mean of the squared deviations. This quantity is called the variance, denoted :
For Set A:
For Set B:
Now the numbers match what the figure shows: Set A has nearly four times the variance of Set B, confirming that its points are indeed more scattered.
Do not confuse the sum of squared deviations with the variance. The sum is useful only as an intermediate step; the variance divides by to give a per-observation measure. Without this division, comparing datasets of different sizes is meaningless.
What Each Symbol Means
- — the -th observation (each integer dot on the number line)
- — the arithmetic mean of all observations (30, marked by the arrow)
- — the deviation of an observation from the mean (the horizontal distance from a dot to the arrow)
- — the squared deviation (always non-negative, solving the sign problem that plagued mean deviation) …